
Appearance
Cold Start
COLD
What it is
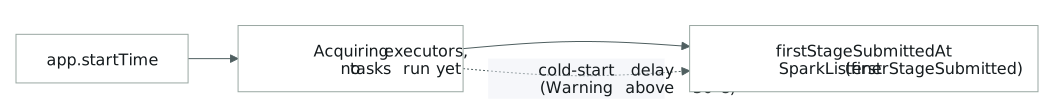
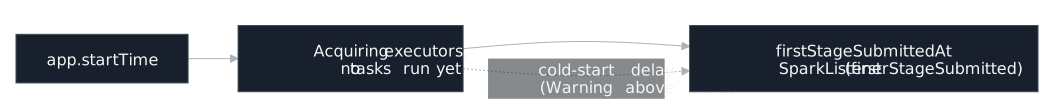
Cold start is the gap between when a Spark application starts and when it actually begins doing work: the delay before the DAGScheduler hands off the first stage for execution. In the event log, that moment is marked by SparkListenerStageSubmitted, whose payload is a direct serialization of a StageInfo: the event name plus the stageInfo and any properties, with no task-level data attached[1]. That shape matches what the event records. The DAGScheduler doesn't pre-schedule the whole DAG upfront (it reacts to stage completions, unlocking child stages one at a time), and once it has carved the DAG into stages and handed a TaskSet for the next stage to the TaskScheduler, only then does the TaskScheduler assign individual tasks to executors[2]. SparkListenerStageSubmitted therefore captures the moment the DAGScheduler creates/submits that TaskSet, before any task has actually been placed on an executor.
How it's detected
firstStageSubmittedAt − app.startTime > 30 s → Warning. firstStageSubmittedAt is a synthetic field: the timestamp of the first SparkListenerStageSubmitted event in the event log.
Why it matters
Because the event carries only stage-level metadata and fires ahead of any executor task placement[1:1][2:1], a large gap here reflects time spent before the DAGScheduler could submit work at all, not time spent inside tasks. It's a signal about scheduling/startup latency, distinct from the per-task metrics that describe work once tasks are actually running on executors.
How to fix it
Dynamic-allocation ramp-up isn't directly tied to firstStageSubmittedAt timing, but the configuration below governs how many executors an application has available at launch, and how reliably that number can grow:
- Size executors deliberately instead of defaulting to one large executor per node. For a 10-node, 16-core/64GB cluster targeting ~5 cores per executor, the standard derivation reserves 1 core per node for daemons (15 usable cores/node, 150 total), divides by 5 cores/executor (30), and subtracts 1 for the YARN ApplicationMaster: 29 executors × 5 cores × ~18GB[3]. Cloudera's equivalent 6-node walkthrough lands on the same shape: 17 executors × 5 cores × 19G, rather than one fat executor per node[4].
- If dynamic allocation is enabled, its ability to add executors at all depends on one of a few supporting mechanisms being turned on. One such mechanism is
spark.dynamicAllocation.shuffleTracking.enabled(defaulttruesince Spark 3.0), which "enables shuffle file tracking for executors, which allows dynamic allocation without the need for an external shuffle service," and "will try to keep alive executors that are storing shuffle data for active jobs"[5]. Without shuffle tracking or an external shuffle service configured, dynamic allocation cannot be enabled at all[5:1].
Deliberate executor sizing plus the dynamic-allocation precondition (values from the 16-core/64GB-node derivation above):
properties
# ~5 cores per executor instead of one fat executor per node
spark.executor.cores=5
spark.executor.memory=18g

# Dynamic allocation, with its required shuffle-tracking precondition (default true since Spark 3.0)
spark.dynamicAllocation.enabled=true
spark.dynamicAllocation.shuffleTracking.enabled=true
Limitations / false-positive risk
Some startup latency is unavoidable: a cluster still has to provision before it can run anything. The signal measures the gap before the first stage is submitted, and that gap can legitimately vary by cluster manager, so a warning here doesn't always mean something is wrong.
Related
- Executor sizing & dynamic allocation: Cluster Tuning